


-
Forest ecosystems harbor abundant, structurally unique secondary metabolites. Multiple tree-derived metabolites possess well-documented pharmacological values, such as paclitaxel from Taxus brevifolia, camptothecin from Camptotheca acuminata, and betulinic acid from Betula platyphylla, which are representative lead molecules for antitumor and anti-inflammatory drug development[1,2]. As perennial woody plants, forest trees differ substantially from annual herbaceous species, generally characterized by high genomic heterozygosity, long generation cycles, and immature genetic transformation systems[3]. Under long-term evolutionary selective pressure, whole-genome duplication events, transposon bursts, and population-level structural variations collectively reshape secondary metabolic pathways and form unique chemical defence systems in woody plants[4].
A single-reference genome only represents genomic information from one individual and loses substantial presence–absence variations (PAVs), copy number variations (CNVs), and structural variations (SVs) closely associated with secondary metabolic traits, making it difficult to interpret metabolic–phenotype divergence within tree populations. With the maturation of long-read sequencing technologies, pan-genomes for several tree species, including poplar (Populus spp.), tea (Camellia sinensis)[5], and oak (Quercus spp.), have been successively published, overcoming the inherent drawbacks of single-reference genomes and laying the data foundations for systematically dissecting secondary metabolic evolution in forest trees[4].
Multi-omics integration has become a mainstream paradigm for dissecting plants' metabolic–regulatory networks. Datasets of pan-genomic variations combined with transcriptomics and metabolomics, via the joint analytical strategies of weighted gene co-expression network analysis (WGCNA) and metabolite-based Genome-Wide Association Studies (mGWAS) combined with expression Quantitative Trait Loci (eQTL), enable identification of hub genes governing secondary metabolism. Coupled with computational biophysical simulations, high-throughput screening systems bridging plants' genomic variations and human drug targets can be established[6].
This work is presented as a Perspective rather than a comprehensive exhaustive literature review. It aims to sort out the complete technical chain ranging from pan-genomic evolutionary dissection and multi-omics hub gene mining, to computational pharmacological translation of tree-derived metabolites, and to analyze scientific questions and technical bottlenecks at each stage, offering insights for research on trees' secondary metabolism and natural product exploitation. This paper concludes by summarizing the core logics and prospecting follow-up research directions (Fig. 1).
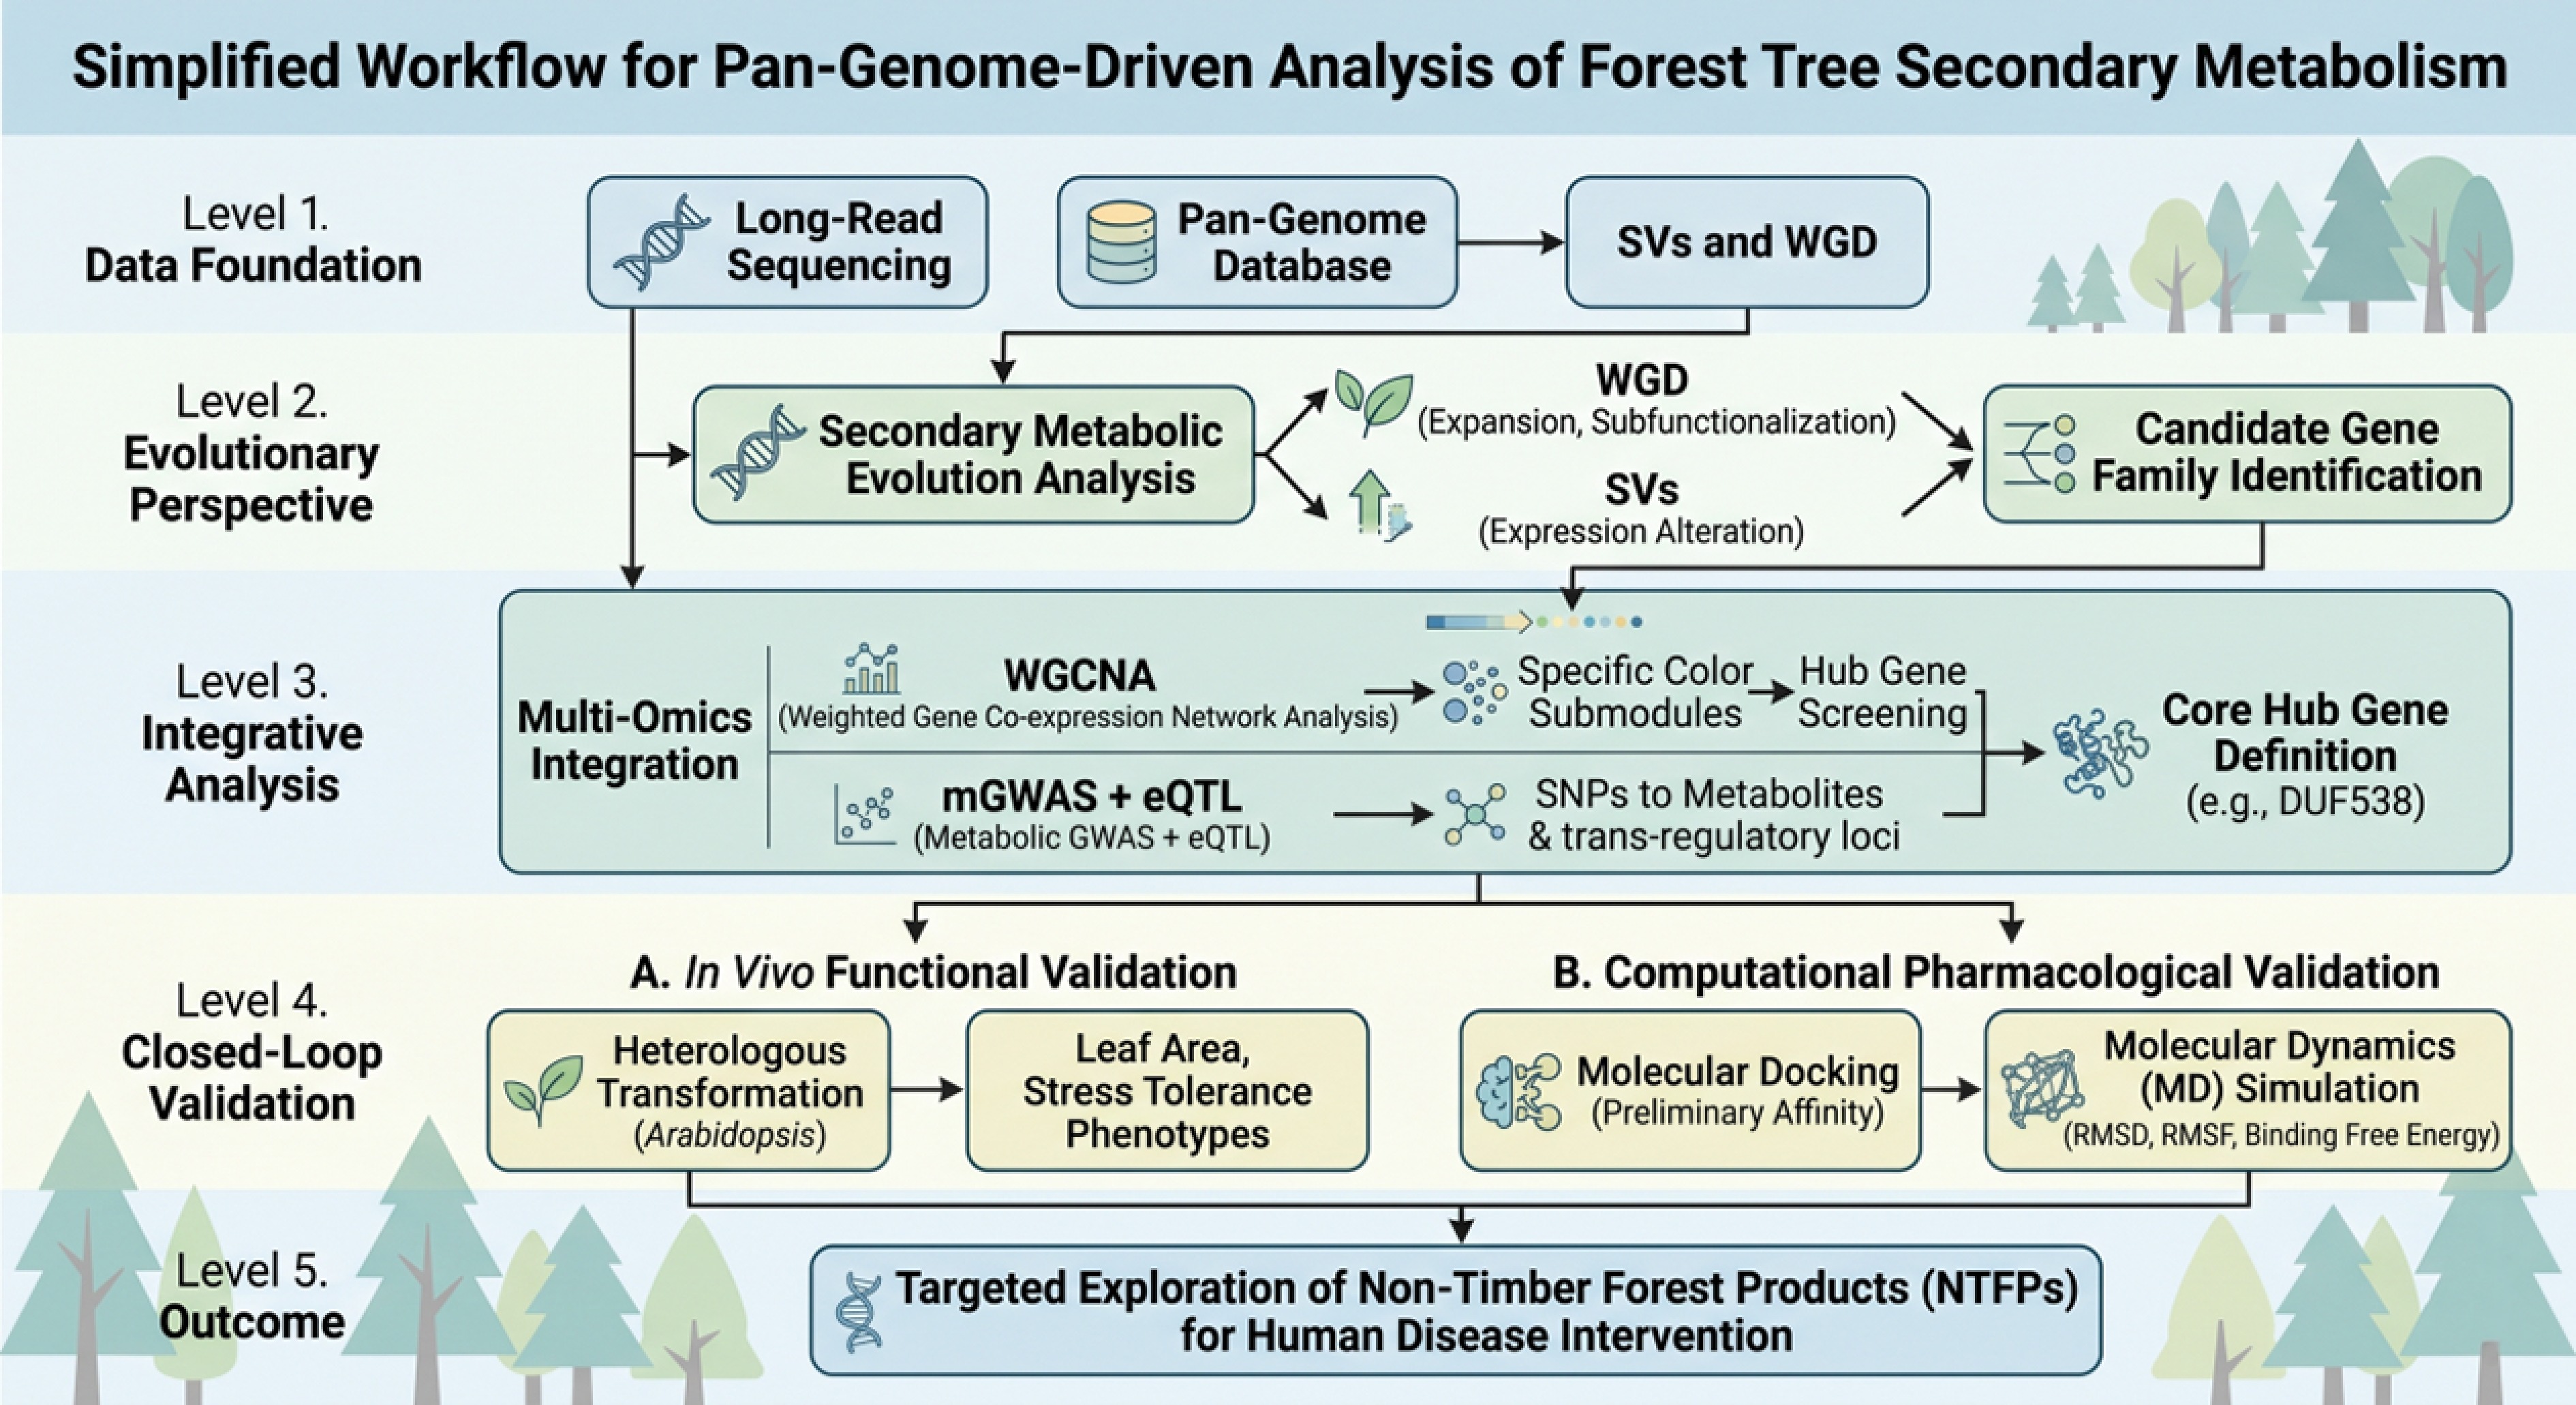
Figure 1.
Schematic diagram of the overall workflow for a pan-genome-driven analysis of secondary metabolism in forest trees. The diagram illustrates the complete technical workflow from pan-genomic data resources, evolutionary analysis, multi-omics integrative analysis, and closed-loop validation to natural product exploitation.
-
Whole-genome duplication (WGD) acts as a core evolutionary force driving the large-scale expansion of plant genomes[7]. Homologous genes generated by duplication achieve spatiotemporal expression divergence through subfunctionalization, and some copies acquire neofunctionalized mutations to remodel secondary metabolic biosynthetic networks[8]. Near-gapless genome assemblies for Pseudocydonia sinensis demonstrate that a Maleae-specific WGD event drove the tandem duplication expansion of phenylpropanoid pathway gene families, accompanied by the amplification of flavonoid biosynthesis-related gene families[9,10]. Phylogenomic analyses of seed plants' pan-genomes show that subfunctionalization contributes to the local adaptive evolution of metabolic pathways; diploidization following polyploidization eliminates large quantities of redundant genes, and retained paralogous genes have endowed forest trees with distinctive chemical defence capabilities.
SV constitutes a core variant category in pan-genome datasets. Compared with single-nucleotide polymorphisms (SNPs), SVs involve large-scale chromosomal rearrangements and can alter cis-regulatory elements in promoter regions; transposon insertions reshape the epigenetic modification status of target genes[11−13]. Pan-genome analyses of 17 poplar (Populus spp.) populations identified 30 PopPLY family members. Ka/Ks calculations indicate purifying selection maintains structural conservation of abscisic acid signalling. Six discrete SVs were detected at Populus euphratica Pyrabactin resistance-like(PYL) loci. Transcriptomic data reveal that these SVs alter transcript abundances of PYL6 and PYL17 and mediate drought-stress-response divergence in root and leaf tissues[14].
A unique merit of pan-genome analysis lies in its capability to capture PAVs and CNVs frequently missed by single-reference assemblies. Such variants are particularly critical for secondary metabolic traits, because gene dosage effects directly modulate metabolic flux. PAVs covering complete biosynthetic gene clusters have been identified in multiple forest tree lineages, confirming SVs as important contributors to interindividual metabolic diversity.
Conventional comparative genomics versus pan-genome analysis in forest trees
-
Conventional comparative genomics mostly relies on a small set of reference genomes and excels at resolving WGD-mediated gene family expansion at species-divergence scales, yet cannot capture intrapopulation PAVs, CNVs, and SVs. Forest trees' pan-genomes enable analyses of intrapopulation genetic variations and address biological questions such as why metabolic phenotypes differ among conspecific individuals. These two approaches are complementary and nonsubstitutable. WGD represents ancient species-scale evolutionary events, whereas PAVs/SVs/CNVs mostly reflect recent population-level adaptive variations, marking their essential distinction in evolutionary timescales[15].
Section summary and limitations
-
Current studies on WGD and the pan-genomes of forest trees still exhibit prominent shortcomings. Most forest trees' pan-genomes are built with limited population sample sizes. Numerous secondary-metabolism-related PAVs are only characterized at the sequence level without supporting metabolic phenotype validations. Biological functions for most duplicated paralogous gene copies remain experimentally uncharacterized[4]. Given such evolutionary understandings, multi-omics approaches are required to identify hub genes governing secondary metabolite biosynthesis from massive genomic variations.
Representative pan-genome–multi-omics case studies for secondary metabolism in forest trees are summarized in Table 1.
Table 1. Representative pan-genome–multi-omics case studies for secondary metabolism research in forest trees.
Species Omics type Core scientific question Key findings Limitations of the study Ref. Pseudocydonia sinensis PacBio gapless genome Impacts of WGD on the phenylpropanoid pathway evolution Maleae-specific WGD drives expansion of phenylpropanoid and flavonoid gene families Only one individual genome; lacks population-level variant information [16] Populus euphratica Pan-genome + transcriptome How SVs regulate stress-responsive metabolic pathways SVs at PYL loci alter gene transcription and modulate drought responses No combined metabolomic analysis; secondary metabolic–phenotype associations are absent [17] Populus tomentosa Pan-genome + mGWAS + eQTL Genetic basis for coumarin metabolism DUF538 is identified as a core gene for coumarin biosynthesis Limited population sample size; no pharmacological translation investigation [18] -
WGCNA represents a classic clustering algorithm for high-throughput transcriptomic data[19]. Conventional analytical workflows prioritize high-weight modules with maximum node counts. Such modules are frequently enriched in housekeeping genes for basal metabolism and show limited overlap with secondary metabolic genes. Therefore, soft threshold parameters should be adjusted to mine specific secondary co-expression submodules. Selection of color specific submodules filters expression noise from housekeeping genes; accurately localizes regulatory networks for flavonoid, phenylpropanoid, and other specialized metabolic pathways; and improves efficiency for hub gene screening[20−22].
The intrinsic limitations of WGCNA include the following. WGCNA only constructs correlation-based co-expression networks and cannot infer causal gene-regulatory relationships. It builds undirected networks from pairwise gene expression correlations and cannot judge regulatory directions or causal flows. Tools such as GENIE3 and GRNBoost2 should be supplemented for causal–regulatory dissection.
mGWAS maps metabolic chemical phenotypes onto genomic variant loci[23]. Combined with eQTL analysis, it further introduces transcriptional regulatory dimensions. In population-level multi-omics studies of Populus tomentosa, mGWAS pinpointed SNP loci associated with coumarin metabolism; eQTL mapped trans-regulatory loci. Coupled with selective sweep analyses, the core gene DUF538 was finally retrieved. Heterologous transformation experiments validated its function in coordinately modulating coumarin-related metabolic flux.
Compared with standalone analytical methods, the combination of the WGCNA submodule strategy and mGWAS-eQTL improves the specificity of hub gene discovery, while possessing clear application boundaries. Cross-platform data dimension discrepancies reduce the goodness-of-fit of statistical models. Conventional dimensionality-reducing algorithms risk discarding functionally critical yet less abundant metabolic nodes. The high heterozygosity of forest trees' genomes introduces substantial background noise[3]. Relative to inbred model plants, this method demands larger population sizes and deeper sequencing coverage.
Multi-omics integration should not be restricted to transcriptome–metabolome dual-omics. Proteomics reflects post-translational regulation and bridges gaps between transcript abundance and metabolic phenotypes[24]. Single-cell and spatial transcriptomics resolve the cellular heterogeneity underlying secondary metabolism and pinpoint specific cell subpopulations responsible for metabolite biosynthesis[25,26]. Nevertheless, high lignification in woody tissues impedes the isolation of protoplasts, and the cell wall's interference hinders the large-scale deployment of single-cell and spatial transcriptomics in forest tree research[27].
Section summary and limitations
-
Existing multi-omics-integrated studies on forest trees are mostly confined to a small number of model tree species. Unified cohort datasets across different tissues and environmental conditions are scarce. Heterogeneity among data generated by distinct sequencing platforms increases difficulties for multi-omics fusion analyses. Multi-omics approaches can retrieve candidate genes and metabolites related to trees' secondary metabolism. However, the ecological defensive activities of tree metabolites do not equate to human pharmacological activities, and remarkable logical gaps exist between them.
-
Forest trees synthesize abundant secondary metabolites against herbivores, pathogenic microorganisms, and oxidative stresses[28,29]. Some of these compounds have been developed into clinical drugs: Paclitaxel from Taxus (a microtubule stabilizer for antitumor therapy), camptothecin from Camptotheca acuminata (a topoisomerase-I inhibitor), and betulinic acid from birch (Betula spp.) (antimelanoma and anti-human immunodeficiency virus (HIV) activities).
Critical logical revision: Some previous literature proposed a "mechanistic parallelism" between the ecological defense functions of plant metabolites and human pharmacological activities, which represents an oversimplification. Although partial phenolic and terpenoid compounds function via electrophilic reactivity, redox modulation, and competitive enzyme inhibition, and such biochemical mechanisms are conserved across biological kingdoms, anti-insect or antimicrobial activities in plants cannot be directly equated to therapeutic efficacy in humans. Species-specific target divergence, in vivo bioavailability, metabolic degradation pathways, and dosage discrepancies collectively prevent ecological bioactivities in plants from translating into pharmacological effects in humans. Ecological activity merely serves as preliminary screening evidence instead of pharmacological proof[30].
It should be noted that classic active molecules such as paclitaxel, camptothecin, and betulinic acid were originally discovered via traditional phytochemistry rather than pan-genomics or multi-omics. The value of pan-genomics and multi-omics lies in resolving their biosynthetic pathways, mining natural population variations, and discovering novel structural analogues.
Three cases of a complete evidence chain
-
(1) Betulinic acid from birch (Betula spp.): pan-genomics resolved the regulatory effects of PAV variations within triterpene biosynthetic gene clusters on betulinic acid accumulation. Molecular dynamics simulations verified the binding of betulinic acid derivatives to the inflammatory targets COX-2 and 5-LOX, and their anti-inflammatory activities have been validated by in vitro cellular assays.
(2) Flavonoid metabolites in poplar (Populus spp.): multi-omics integrative analyses identified MYB family hub genes governing flavonoid biosynthesis and accumulation. Computational simulations evaluated their binding potentials to PPARγ and α-glucosidase and suggested hypoglycemic prospects, which await further wet-lab validations.
(3) Paclitaxel biosynthetic pathway in Taxus: pan-genomics identified SV variations modulating the expression of taxadiene synthase gene families and altering paclitaxels' biosynthetic capacity. Anticancer targets of paclitaxel are well supported by abundant experimental evidence.
Representative bioactive secondary metabolites derived from forest tree species are compiled in Table 2.
Table 2. Representative bioactive secondary metabolites derived from forest tree species.
Tree species Secondary metabolite Biosynthetic pathway Pharmacological target Evidence level Ref. Taxus brevifolia Paclitaxel Terpenoid biosynthetic pathway Tubulin In vitro + in vivo experimental evidence [31] Camptotheca acuminata Camptothecin Terpenoid–indole–alkaloid pathway Topoisomerase I In vitro + in vivo experimental evidence [32] Betula platyphylla Betulinic acid Triterpenoid biosynthetic pathway COX-2, 5-LOX In vitro cellular assays; computational simulations [33] Populus spp. Flavonoids Flavonoid biosynthetic pathway PPARγ, α-glucosidase Computational prediction only;
experimental validations pending[34] Forest trees have experienced recurrent WGD events and long-term adaptive evolution, conferring great potential to generate structurally diverse specialized metabolites and rendering them valuable resources for natural-product-based drug discovery[9].
-
After the candidate genes have been predicted by bioinformatic analyses, heterologous transformation systems deliver functional evidence at macroscopic phenotypic levels[35−37]. Nevertheless, molecular-level physical evidence is required for applying tree-derived metabolites in research into human disease interventions. Molecular docking involves a preliminary assessment of molecular steric hindrance and electrostatic complementarity at the binding interfaces. Molecular dynamics (MD) simulations further resolve the thermodynamic stability of bound complexes. The GROMACS package executes 100-nanosecond trajectory simulations with Optimized Potentials for Liquid Simulations All-Atom (OPLS-AA) force-fields, while the LigParGen server generates small-molecule topological parameters[38,39].Outputs including Root Mean Square Deviation (RMSD), Root Mean Square Fluctuation (RMSF) and Molecular Mechanics Poisson-Boltzmann Surface Area (MM-PBSA) binding free energies provide atomistic-scale descriptions for ligand–receptor interactions[40,41].
Key clarification: MD simulation is a hypothesis-generating predictive tool and is not equivalent to pharmacological experimental validation. Confirmation of pharmacological efficacy necessitates in vitro enzyme inhibition assays, cellular function tests, and ultimately in vivo animal efficacy models. Computational pharmacology functions to prioritize candidate molecules at high throughput and to narrow down candidate pools for subsequent experimental validations.
Complete in silico pharmacological assessment also incorporates ADMET prediction. Machine learning models evaluate oral bioavailability, penetration of the blood–brain barrier, cytochrome-P450 metabolism profiles, and hepatotoxicity risks so that compounds with poor pharmacokinetic properties can be eliminated ahead of resource-intensive wet-lab experiments.
Section summary and limitations
-
Numerous secondary metabolites from forest trees possess complex stereochemical structures. The lack of well-adapted force-field parameters for some small molecules compromises the reliability of simulations' outputs. Although the complete technical chain combining pan-genomics, multi-omics, and computational pharmacology has been established, multiple technical bottlenecks restrict translational applications of natural products originating from forest trees.
The input, output, advantages, and limitations of core computational–pharmacology workflows applied to tree-derived natural products are listed in Table 3.
Table 3. Input, output, advantages, and limitations of core computational pharmacology evaluation workflows applied to tree-derived natural products.
Workflow Input Output Advantages Limitations Ref. Molecular docking Proteins' 3D structure, small-molecule structure Preliminary binding modes and docking scores High throughput, fast computation speed Static model; ignores proteins' conformational dynamics; relatively high false positive rates [41] Molecular dynamics simulation Docked complex, force-field parameters RMSD/RMSF, binding free energies Atomistic-scale dynamic characterization of molecular interactions High computational resource consumption; force-field parameter deficits for complex natural products [42] ADMET prediction 2D/3D small-molecule structures Pharmacokinetic and toxicity risk profiles Early elimination of candidates with poor druglikeness Performance depends on the training datasets; prediction accuracy is limited for tree-specific metabolites [43] 2D: 2-dimension; 3D: 3-dimension; RMSD: Root Mean Square Deviation; RMSF: Root Mean Square Fluctuation. -
(1) Pan-genomic level: Most forest trees' pan-genomes are constructed with limited population sizes. Many secondary metabolism-related PAVs/CNVs are only sequenced without matched metabolic phenotype datasets, leading to severely insufficient functional annotations[44].
(2) Multi-omics level: High sequencing costs restrict large-population multi-omics studies on forest trees. Data heterogeneity arising from different experimental platforms creates obstacles for fusion analyses. The characteristics of woody samples hinder the large-scale deployment of single-cell and spatial transcriptomics.
(3) Pharmacological translation level: Cases with complete evidence chains from genomic variations to in vivo pharmacological efficacy are rare. Plenty of computationally screened candidate metabolites lack follow-up wet-lab validations.
Practical future research directions
-
(1) Construct tree-specific pan-genome-metabolome population cohorts, integrating genotype and metabolic phenotype datasets to decipher the functional effects of secondary metabolism-associated PAVs.
(2) Develop multi-omics-integration algorithms adapted to highly heterozygous tree genomes to reduce background noise and improve the accuracy of hub gene identification.
(3) Establish standardized closed-loop workflows: Pan-genome mining → multi-omics screening → in vitro functional validation → high-throughput computational pharmacology prioritization → cellular / in vivo animal efficacy validation. It must be emphasized that computational simulations cannot replace experimental assays.
(4) Promote applications of deep learning-based artificial intelligence (AI) in SV detection, metabolite structure interpretation, and virtual compound screening, while objectively acknowledging the limitations of AI-driven predictions[45].
(5) Leverage the strengths of single-cell and spatial transcriptomics to resolve spatiotemporal cellular specificities underlying secondary metabolite biosynthesis.
Section summary and limitations
-
Overall, research concerning forest trees' secondary metabolism remains at an early interdisciplinary fusion stage. Specialized cohort resources, tailored analytical algorithms, and multilayer experimental validation systems are yet to be further improved. Synthesizing evolutionary dissection, multi-omics mining, and computational pharmacology evaluations, we draw general conclusions for this manuscript.
-
Long-read-sequencing technologies have pushed forest tree research into the pan-genomic era. WGD events, together with population-level SV/PAV/CNV variations, co-drive the evolutionary remodeling of secondary metabolic pathways in forest trees. Multi-omics-integrated strategies enable the identification of regulatory hub genes for secondary metabolism from massive genomic variations. Computational pharmacology tools such as molecular dynamics and ADMET prediction support high-throughput assessments of interactions between tree-derived metabolites and human targets and accelerate screening for natural lead compounds.
Nevertheless, this whole technical chain still has prominent drawbacks. Construction of pan-genome cohorts for forest trees is inadequate, and technical obstacles persist for multi-omics-data fusion. Cases with complete experimentally validated evidence chains linking tree genomic variations to bona fide pharmacological activities are scarce. Predictions from computational simulations must be verified via multilayer wet-lab experiments and cannot be directly regarded as evidence for pharmacological efficacy.
From a Perspective viewpoint, this paper outlines a closed-loop workflow for mining natural products from forest trees. We hope to foster interdisciplinary intersections among evolutionary genomics, multi-omics, and computational pharmacology, and promote translational research converting nontimber forest product resources into drug leads[46].
-
The authors confirm their contributions to the paper as follows: Study conception and design: Cao R, Song X; data collection: Feng Y, Zhang S, Nie F; analysis and interpretation of the results: Feng Y, Zhang S, Nie F, Cao R, Song X; draft manuscript preparation: Feng Y, Cao R. All authors reviewed the results and approved the final version of the manuscript.
-
Data sharing is not applicable to this article as no datasets were generated or analyzed during the current study.
-
The authors declare that they have no conflict of interest.
- Copyright: © 2026 by the author(s). Published by Maximum Academic Press, Fayetteville, GA. This article is an open access article distributed under Creative Commons Attribution License (CC BY 4.0), visit https://creativecommons.org/licenses/by/4.0/.
-
About this article
Cite this article
Feng Y, Zhang S, Nie F, Cao R, Song X. 2026. Pan-genome-driven analysis of forest trees' secondary metabolism: from multi-omics integration to computational pharmacological evaluation. Forestry Research Advances 1: e018 doi: 10.48130/fra-0026-0016 
Pan-genome-driven analysis of forest trees' secondary metabolism: from multi-omics integration to computational pharmacological evaluation
- Received: 29 June 2026
- Revised: 20 August 2026
- Accepted: 17 September 2026
- Published online: 15 October 2026
Abstract: Forest trees produce structurally diverse secondary metabolites, which serve as vital defensive compounds against biotic and abiotic stresses and constitute important resources for natural-product-derived drug leads. Compared with annual herbaceous model plants, forest trees exhibit biological features including highly heterozygous genomes, long generation times, and abundant population-level structural variations. Conventional single-reference genomes cannot fully capture presence–absence variations (PAVs), copy number variations (CNVs), and large-scale structural variations (SVs) that are relevant to secondary metabolism, which restricts the efficiency of mining pharmacologically valuable metabolites from forest trees. Pan-genomics provides a new research framework for deciphering the evolution of trees' secondary metabolism, enabling a systematic dissection of how whole-genome duplication (WGD) and population-level structural variations shape secondary metabolic gene families. Multi-omics integration strategies such as weighted gene co-expression network analysis (WGCNA), metabolite-based Genome-Wide Association Studies (mGWAS), and expression Quantitative Trait Loci (eQTL) facilitate the identification of hub genes regulating metabolite biosynthesis. Computational pharmacological approaches, including molecular docking, molecular dynamics simulations, and Absorption, Distribution, Metabolism, Excretion and Toxicity (ADMET) prediction, support high-throughput virtual screening of candidate compounds. Nevertheless, computational simulations only generate scientific hypotheses and cannot substitute for in vitro and in vivo pharmacological experimental validation. As a Perspective article, this paper constructs a closed-loop technical pipeline: Pan-genomic dissection of variation → multi-omics identification of hub genes → computational pharmacological evaluation for mining natural products from forest trees. We systematically analyze the technical merits, intrinsic limitations, and practical bottlenecks of each step within this pipeline and propose priority directions for future research, providing references for drug translation research of nontimber forest products.